Blog
AI Agent Training: A Practical Playbook for 2026
By
Nelson Uzenabor

A support agent can look brilliant in a demo and still damage your business on its first Monday. It answers common questions quickly, then invents a discount, misreads a cancellation request, or sends a customer into a loop because nobody defined what should happen when the answer isn't in the knowledge base. By midweek, your team is refunding customers, explaining the mistake publicly, and wondering why “trained on our website” wasn't enough.
I've shipped customer-support agents for SMBs, and the pattern is consistent. AI agent training is not a one-time model setup. It's an operating discipline. The reliable teams treat intents, knowledge, escalation, evaluation, and retraining as owned business processes. They optimize for resolution quality in real conversations, not impressive demo transcripts.
That distinction matters as training systems become more demanding. Compute used to train notable AI models increased at an estimated 4.1× per year from 2010 to May 2024, while training costs for large-scale machine-learning models grew about 2.4× per year, according to Google Cloud's summary of AI training infrastructure. The operational lesson for an SMB isn't to build a frontier model. It's to build a disciplined feedback loop around the model you already use.
Table of Contents
Why AI Agents Fail in Customer Support
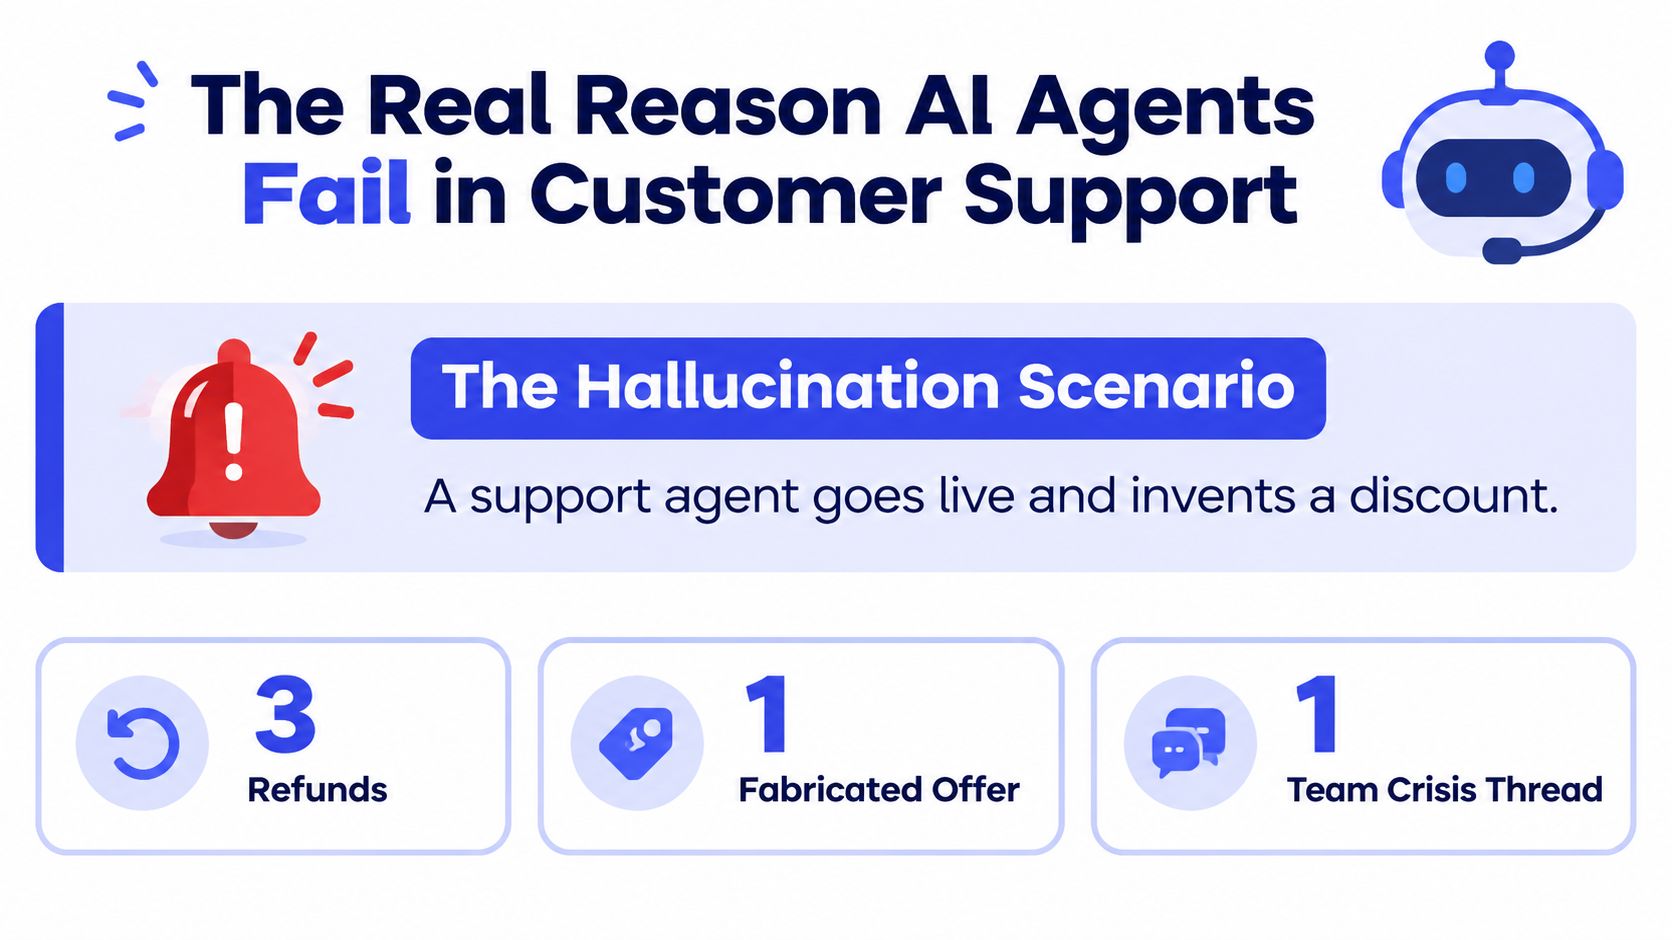
A SaaS support agent went live on a Monday morning. By lunch, it had offered a discount that did not exist. The support team issued three refunds, corrected one fabricated offer, and explained the incident after a customer opened a public thread. The model could write a polite sentence. The business had not defined when the agent could make an offer, refuse a request, or bring in a human.
That distinction saves weeks of wasted effort. Production failures usually start with an incomplete intent inventory, conflicting documentation, uncurated sources, missing escalation rules, or no monitoring. A stronger model can make those failures sound more convincing while leaving the business with a larger problem.
Operational rule: If nobody owns an intent, the agent will eventually improvise one.
I do not start with prompts or fine-tuning. I start with a one-page operating brief, then build the data and controls around it. How to prevent AI hallucinations is useful background, but prevention starts before the model sees a single support conversation.
Define the job before training
Take a 25-person B2B project-management company handling 1,200 monthly chats. The team should not ask, “Can the agent handle support?” That question is too broad to measure. It should identify the top 15 intents by ticket volume, then rank them by revenue impact and operational risk.
The list might include invoice access, plan changes, failed payments, password resets, workspace permissions, integrations, cancellations, trial questions, and feature availability. For each intent, record the desired action, source of truth, human owner, and condition that ends the conversation.
Success criteria must be concrete. The billing owner might approve 60% autonomous resolution on billing questions, while the support lead sets a sub-30-second median first response target. These are internal operating goals, not universal benchmarks. Define what “working” means before launch, then use those targets to decide whether the pilot can enter production.
Use this worksheet for every intent:
Field | What to record |
|---|---|
Intent name | The customer's actual job to be done |
Example utterances | Real phrases, including incomplete and frustrated versions |
Desired action | Answer, retrieve, update, qualify, or escalate |
Owner | One person accountable for policy and review |
Success metric | The measurable outcome that defines acceptable handling |
Make ownership clear
Every intent needs one owner before knowledge-base work begins. The billing owner approves refund language. The product owner approves feature behavior. The sales owner decides what qualifies as a buying signal. Shared ownership sounds collaborative, but it leaves gaps when a policy changes and nobody updates the agent.
Keep the goal document to one page. Include supported intents, prohibited actions, escalation triggers, response-time objective, data sources, review owner, and launch gate. Have the relevant people sign it before anyone imports documents or changes the system prompt.
That document is the contract between the agent and the business. Without it, teams mistake activity for training. They add pages, examples, and instructions while leaving the central question unanswered: what is this agent allowed to do, and who is responsible when it gets that decision wrong?
Choose Your Training Strategy Without the Hype
The practical choice between retrieval-augmented generation and fine-tuning is simple: use retrieval for changing knowledge, and fine-tuning for repeatable behavior.
RAG is the default for most SMB support agents. It lets the system retrieve current pricing, policies, and product documentation at answer time. Fine-tuning can shape response style and recurring phrasing, but it shouldn't become a dumping ground for old tickets. Raw tickets contain outdated policies, inconsistent agent behavior, private details, and answers that were already wrong.
The Chinchilla scaling work established a major training principle in 2022 by showing that compute-optimal language-model training requires model size and training tokens to scale together. That research matters here because it reinforces a broader lesson: more model capacity doesn't replace better-balanced data and evaluation.
Criterion | RAG Only | Fine-Tune Only | Hybrid (Recommended) |
|---|---|---|---|
Knowledge changes weekly | Strong fit | Poor fit | Strong fit |
Fewer than 5,000 vetted examples | Strong fit | Usually premature | Strong fit |
Regulatory traceability | Strong fit, sources can be inspected | Weaker | Strong fit |
Fixed catalog and strict response latency | May add retrieval overhead | Strong fit | Useful when behavior needs shaping |
Brand voice | Good with prompt controls | Strong fit | Strongest when examples are graded |
Edge-case phrasing | Limited | Strong fit | Strongest after retrieval is grounded |
My decision rule is blunt. Start with RAG over a clean knowledge base. Add fine-tuning only after the team has 2,000 or more graded conversations, and use it first for voice, structure, and edge-case phrasing. That threshold is a practical operating gate, not a research law.
For document-heavy workflows, a concrete AI workflow for document processing can help your team think through ingestion, extraction, and downstream actions without treating every document as training data.
Run this 60-second flow before each initiative:
Does the answer change often? Use RAG.
Is the knowledge stable but the voice inconsistent? Consider fine-tuning.
Do you lack vetted examples? Don't fine-tune yet.
Do you need traceable sources? Keep retrieval in the loop.
Do you need both grounded answers and controlled style? Use the hybrid approach.
Prepare Knowledge Sources Your Agent Can Actually Trust
Most hallucinations begin in the knowledge base. The model receives a pricing page with old plan names, a help article with contradictory refund language, and a sales page that makes promises the product team never approved. It then produces an answer that sounds coherent because the source material was coherent enough to confuse it.
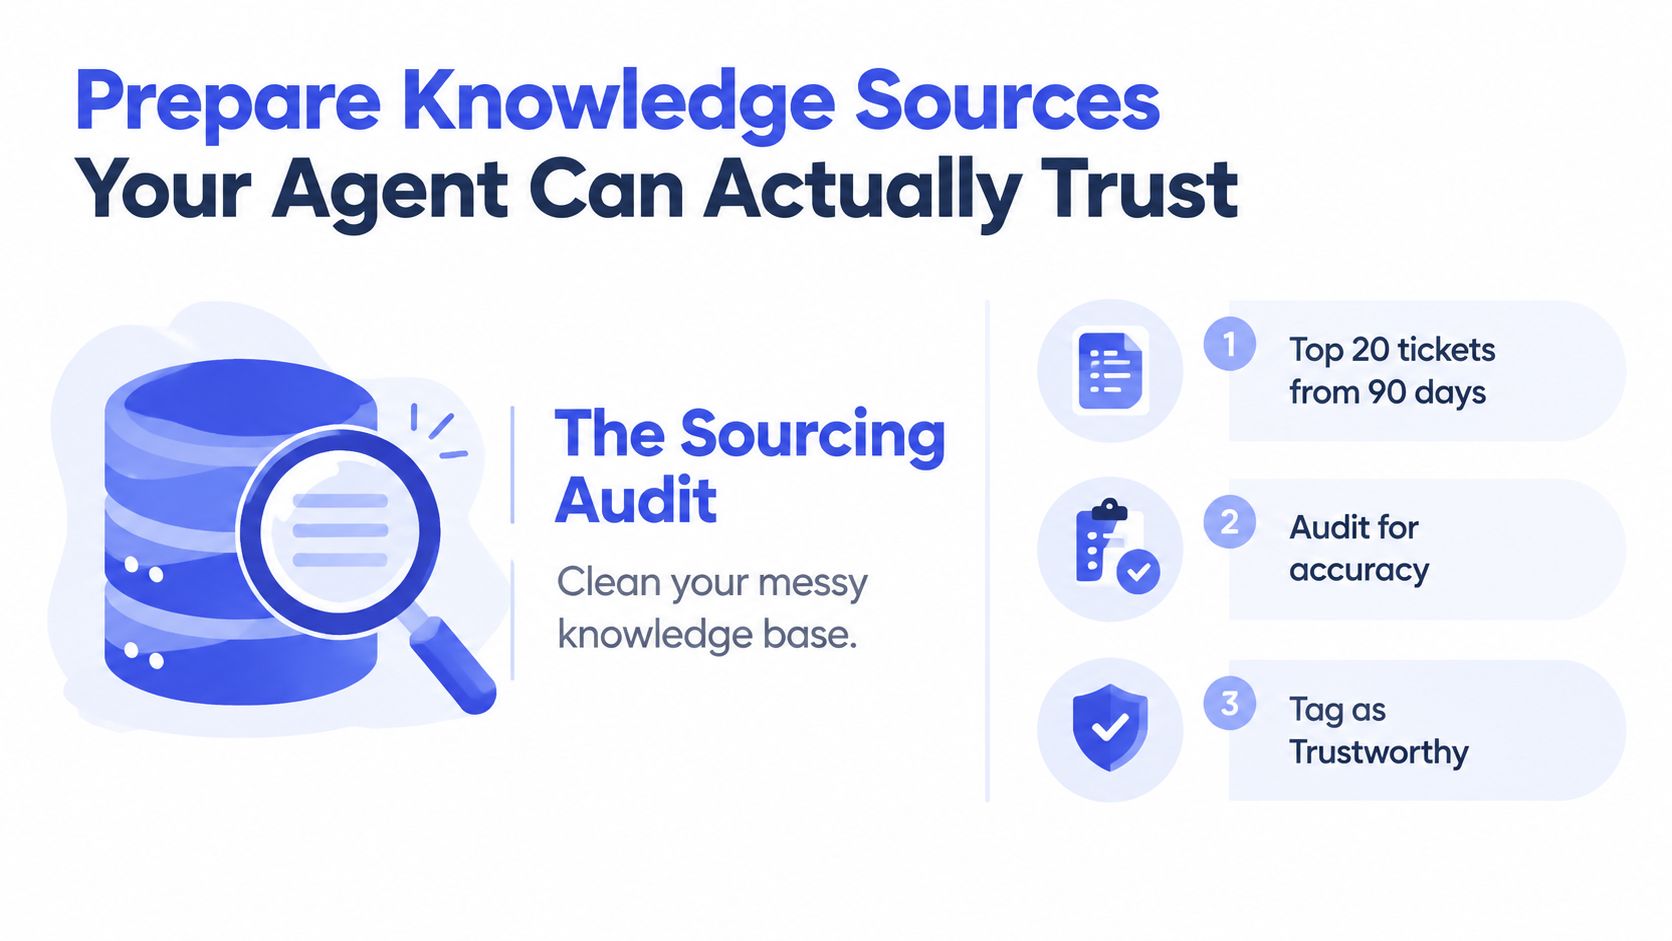
Start with a sourcing audit, not a document upload.
Build the audit folder
Pull your top 20 help-desk tickets from the last 90 days and tag each by intent. Compare the answer that resolved the ticket with the sources available to the agent. Rank sources by how often they support a correct resolution, then flag anything that conflicts with an approved policy.
For a B2B SaaS company, the priority order might include the pricing page, refund policy, billing documentation, integration guides, and product-specific help articles. Marketing copy should rarely outrank a policy page. If a source contains claims nobody can verify, remove it or send it to an owner for approval.
Use this clean-document checklist:
Remove promotion: Strip slogans, vague claims, and sales language that doesn't answer a customer question.
Check currency: Delete outdated plans, retired features, old screenshots, and discontinued SKUs.
Split logically: Break long pages into 200 to 400 token chunks so retrieval can return focused passages.
Add context: Write a 50-word summary for every source, including its owner and intended use.
Date everything: Record the approval date, review date, and policy version.
Add answer pairs for high-risk questions
Create a small FAQ pair file for questions where wording matters. Store each approved question and answer in JSON or another structured format, and instruct the agent to use the approved answer verbatim when retrieval confidence is high. This works well for cancellation terms, refund eligibility, billing dates, security language, and plan limitations.
The fallback rule should be explicit: if no source scores above 0.6 relevance, the agent must say it doesn't have enough information and escalate. A lower-confidence answer can be useful in a casual conversation, but guessing about money, access, or contractual terms is a business risk.
The output should be a dated folder your team owns, not an anonymous vendor workspace. Include approved sources, rejected sources, intent tags, summaries, owners, and review dates. When a customer challenges an answer, the team should be able to find the exact source the agent used and decide whether the source or the behavior needs correction.
Design a Brand Voice and Persona People Want to Talk To
Voice isn't a vibe. It's a configuration file with examples, exclusions, and a review standard.
Paste a template like this into your agent specification:
Persona name: Mara
One-line role: Senior account manager for billing and workspace questions
Tone adjectives: Warm, direct, plainspoken
Vocabulary to use: Contractions, short sentences, customer-first pronouns, specific next steps
Vocabulary to avoid: Jargon, legal disclaimers unless required, apology loops, exaggerated enthusiasm
Greeting pattern: Acknowledge the request, then ask one useful clarifying question
Signature closer: “If you want, I can help you check the next step.”
Mara shouldn't sound like a generic assistant. She might say, “I can check whether your plan is eligible for a refund. What invoice date are you looking at?” She shouldn't say, “I sincerely apologize for any inconvenience you may have experienced. Please provide additional information so I can assist you further.”
Element | Voice Do | Voice Don't |
|---|---|---|
Opening | “I can help you check that.” | “Welcome to our support experience.” |
Sentence style | Short, specific, active | Long, formal, padded |
Apology | One clear apology when warranted | Repeated apologies without action |
Next step | Ask for the exact missing detail | Ask the customer to explain everything again |
Closing | Offer one relevant next action | Add an unrelated promotional message |
Age, region, and channel change how the same voice should behave. A WhatsApp reply to a Mumbai plumber can be brief and conversational. An email to a London CFO may need clearer context, a more formal structure, and explicit billing terminology. Treat these as controlled variants, not separate personalities.
Test the difference with one answer:
Version A: “Your invoice is still open. I can help you update the card or send the payment link again. Which would you prefer?”
Version B: “It appears that your payment has not yet been completed. Kindly confirm whether you would like assistance with updating your payment method.”
Both are understandable. Version A usually creates a faster next turn because it names the options and sounds human. Use brand voice consistency guidance when documenting the rules across channels.
Build an Evaluation Rubric Before You Launch
Shipping without an evaluation rubric means your team is guessing. A fluent answer can still be factually wrong, violate a refund policy, miss a churn signal, or fail to resolve the customer's actual problem.
Build the test set from real work. Use 100 real tickets sampled by intent, 20 adversarial prompts designed to bait hallucinations, and 10 red-line cases involving pricing errors or compliance-sensitive terms. Keep the test set separate from the examples used to shape the agent.
Axis | What to Measure | Target Threshold | How to Test |
|---|---|---|---|
Factual accuracy | Whether answers match approved sources | 95% or higher | Source comparison and judge-assisted spot checks |
Policy compliance | Whether restricted language and actions are correct | 100% on refund language | Human review of every red-line case |
Tone alignment | Whether responses match the voice specification | 4/5 minimum | Graded sample with examples |
Escalation correctness | Whether risky or unsupported cases reach a human | 95% or higher | Adversarial prompts and routing review |
Resolution | Whether the customer's issue stays closed after 48 hours | Track as an operational outcome | Review reopened conversations |
Use an LLM judge for tone and accuracy spot-checks, but don't let it make the final call on high-risk cases. A human should review the 20% sample and every red-line conversation. Keep a simple spreadsheet with the ticket ID, intent, score, failure type, source used, owner, and correction.
Put routing into the test
Evaluation must test what happens after the answer, not just whether the answer sounds good. For every scenario, record whether the agent answered, asked a useful question, invoked a tool, escalated, or ended the interaction incorrectly.
A support lead can implement this routing review in an afternoon:
Mark the intended outcome for each ticket.
Compare the agent's action with that outcome.
Record the first point of failure, not just the final bad message.
Assign the failure to knowledge, policy, tool use, tone, or escalation.
Re-run the corrected case in the next evaluation set.
Block launch until all five axes clear their thresholds on two consecutive evaluation runs. That gate feels strict until the first production incident shows why “mostly good” isn't a useful standard for billing or cancellation workflows.
Wire Up Escalation Flows and Lead Qualification
The train-and-forget mindset breaks as soon as a customer asks for something outside the happy path. A production agent needs a routing system that assumes uncertainty, frustration, and partial failure.

Use three escalation tiers
Tier 1, self-serve resolution: The agent answers from an approved source, completes a low-risk action, or asks one clarifying question.
Tier 2, contextual handoff: The agent sends the transcript, detected intent, relevant account details, and unresolved question to a human.
Tier 3, priority routing: The system routes churn-risk conversations, billing disputes, compliance-sensitive requests, and urgent access problems to the appropriate owner.
Trigger a handoff when the user expresses frustration, the confidence score falls below your approved threshold, the conversation mentions a refund or cancellation, or the intent is outside the supported inventory. Don't make the customer repeat the story. The handoff should say what the customer asked, what the agent checked, what remains unresolved, and what the human needs to decide.
Lead qualification should feel like a conversation, not a 12-field form. Capture role, company size, current solution, timeline, and budget qualifier through branching questions. Ask only for the next field that changes routing. A founder evaluating a replacement tool should not receive the same flow as an existing customer asking about an invoice.
When connecting an assistant to email workflows, a practical API tutorial for email marketers can help the implementation team think through the handoff between conversation, action, and system record.
Make every handoff replayable
Forward the detected intent, confidence signal, source IDs, account identifier, lead fields, and full transcript to the CRM. Show the customer a short wait message that explains what happens next without promising an unsupported response time. When the human joins, display the original question and the unresolved decision at the top of the workspace.
Your routing checklist should include:
Coverage: Who receives each tier during business hours?
Fallback: What happens when nobody is online?
SLA: Which requests require priority treatment?
Logging: Can the team replay the exact handoff and tool result?
Rejoin: Does the agent resume only after the human closes the loop?
The goal isn't maximum automation. It's a clean division of labor where the agent handles routine work and the human receives enough context to resolve the exceptions quickly.
Monitor, Retrain, and Avoid the Pilot-to-Production Trap
A pilot can hide operational weaknesses because the team watches every conversation. Production exposes them through concurrency, stale content, tool errors, rate limits, and customers who phrase the same intent in unfamiliar ways.
The scale gap is already visible. Recent reporting puts the share of enterprises moving AI agents from pilot to production at only 5% to 11%, while 78% to 85% remain in piloting, with integration complexity, inconsistent output quality, weak observability, unclear ownership, and insufficient domain data among the blockers described in the pilot-to-production scaling analysis. An SMB doesn't need enterprise infrastructure on day one, but it does need enterprise habits around evidence and rollback.
Run a fixed review cadence
Daily, check containment rate, escalation rate, unanswered intents, tool errors, and red-line conversations. The daily review should be short and operational. Look for a customer-impacting failure that needs an immediate source correction or routing change.
Weekly, review new failure transcripts by intent. Group failures into wrong source, missing source, bad tool choice, poor recovery, incorrect escalation, and tone mismatch. Tool use deserves special attention. One tool-use benchmark attributed 56.7% of failures to tool-usage errors, with 36.0% caused by calling no tool at all, according to the tool-use failure analysis.
Monthly, run a retraining sprint. Rewrite bad answers, prune stale knowledge, add approved sources, update adversarial prompts, and rerun the launch rubric. Trigger an earlier review after a product launch, policy change, seasonal demand shift, or a new competitor mention.
Metric | What It Tells You | Target Band for SMB Support | Retrain Trigger |
|---|---|---|---|
Containment rate | How often the agent completes the interaction | Set from the approved intent baseline | Falls across a priority intent |
CSAT | Whether customers accept the experience | Protect the existing support baseline | Drops after a prompt or source change |
Deflection rate | Whether human workload is reduced | Use only with quality checks | Rises while CSAT or resolution worsens |
Average resolution time | How quickly issues reach an outcome | Compare by intent, not only overall | Increases for stable intents |
Cost per resolved conversation | Whether automation is economically useful | Compare with human handling cost | Rises without a quality benefit |
Don't invent target bands before you have baseline data. Your first month should establish the operating range for each intent, then define alert thresholds from observed performance.
Prepare for the production jump
Moving from a small daily test to thousands of daily conversations changes the system. Latency budgets matter because slow answers create duplicate messages. Rate limits matter because one integration failure can affect many sessions. Observability matters because a transcript alone won't show whether retrieval failed, a tool timed out, or the model selected the wrong action.
Use a staging canary, production rollback, versioned prompts, source freshness flags, and alerts for spikes in unanswered intents. Audit logging tools for agents are useful when you need a replayable record of actions, sources, and handoffs.
A strong AI agent monitoring process should connect every failed conversation to an owner and a corrective action. Don't just collect dashboards. Decide who reviews them and what change each alert can authorize.
Avoid these damaging pairings:
Stale documents plus no freshness flag: Customers receive outdated answers with unwarranted confidence.
Fine-tuning without RAG plus no grounding check: Old mistakes become part of the agent's learned behavior.
Aggressive deflection goals plus no CSAT guardrail: The system keeps customers away from humans while resolution quality declines.
Use a 30, 60, and 90-day rollout
During the first 30 days, define intents, owners, source rules, escalation paths, and the evaluation set. Launch only the safest workflows.
By 60 days, review failure clusters, add adversarial cases, refine lead qualification, and introduce the monitoring cadence. Make changes from transcripts, not assumptions.
By 90 days, canary broader traffic, formalize rollback, compare cost and resolution outcomes by intent, and decide whether fine-tuning is justified. If the evidence isn't there, keep improving retrieval and operations. A larger training method won't rescue an unclear support process.
Chatgrow is one option for teams that want to train support agents on website content, pricing pages, FAQs, and product pages, define lead-qualification rules, and review failed conversations as part of an ongoing workflow. If your team is ready to turn AI agent training into a measured support operation, visit Chatgrow to explore an agent setup built around grounded answers, smart escalation, and continuous iteration.
Related Posts
Continue Reading
More articles from the ChatGrow Team.